JingxuanC/causal-memory
causal-memory
Causal memory layer for AI agents — MCP server that records decision→outcome relationships. Survives compaction.
Install
npx @deepseek-ai/dsh plugin --profile web add "$PWD/dsh-plugin"`Restart `dsh web` after install. Bundle APIs can change during the developer preview.
README badge
[](https://dshhub.dev/plugins/causal-memory)Paste this into your README. The star count updates with every catalog sync.
From the README
Excerpt from JingxuanC/causal-memory, cleaned of badges and images.
causal-memory
An agent memory system with a causal core — and the only one that models inhibition.
Facts, temporal state, and
decision → outcomecausal edges on one SQLite store, powered by a hippocampus-style engine: typed spreading activation (excitatory and inhibitory), Hebbian co-occurrence reinforcement, Q-value dynamics, and immutable SWR consolidation. Agents recall what happened, when it was true, why it worked — and what would happen if they acted differently.
English · 简体中文
Why
Every agent forgets why it made past decisions after a few context compactions. It re-fixes the same bug the same wrong way, re-debates the same architecture choice, relearns the same lesson.
This happens because causal information is the most fragile type under text compaction. Real-LLM benchmark (grok-build's production compaction prompt):
| Compactions (k) | Textual recall | Causal-table recall |
|---|---|---|
| 1 | 100% | 100% |
| 2 | 85% | 100% |
| 3 | 55% | 100% |
| 5 | 45% | 100% |
The causal table survives because it lives outside the agent's context window — compaction cannot touch it.
Demo
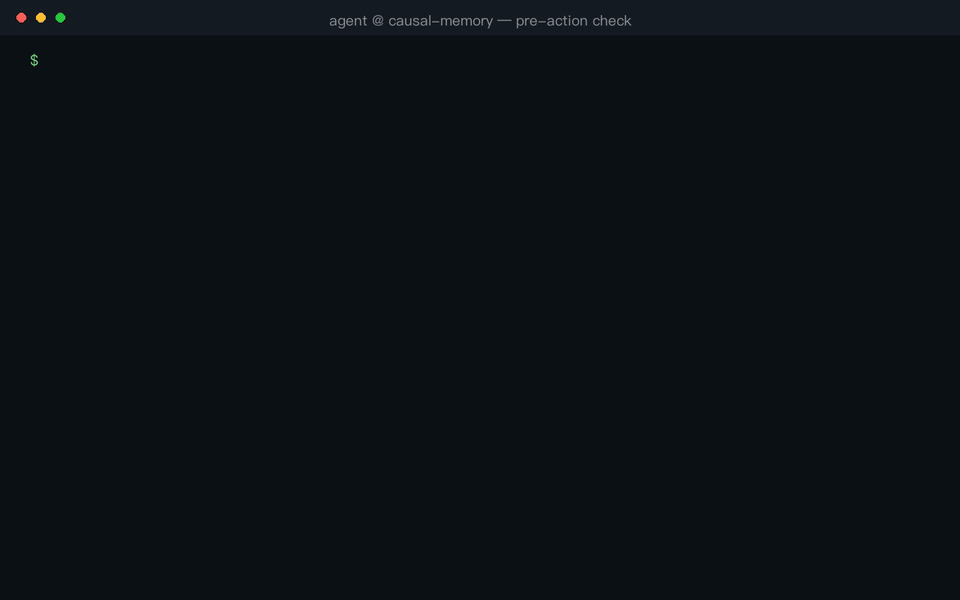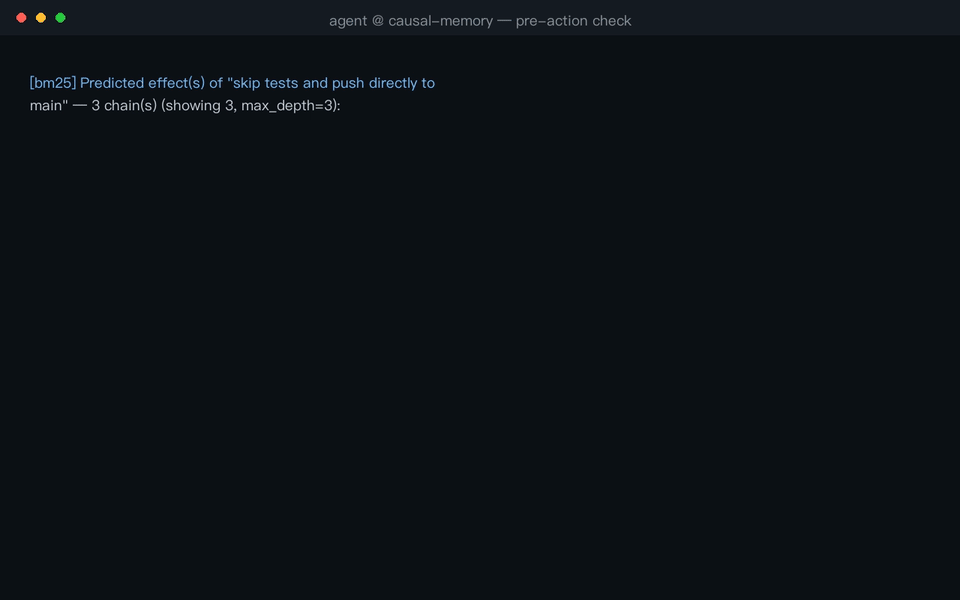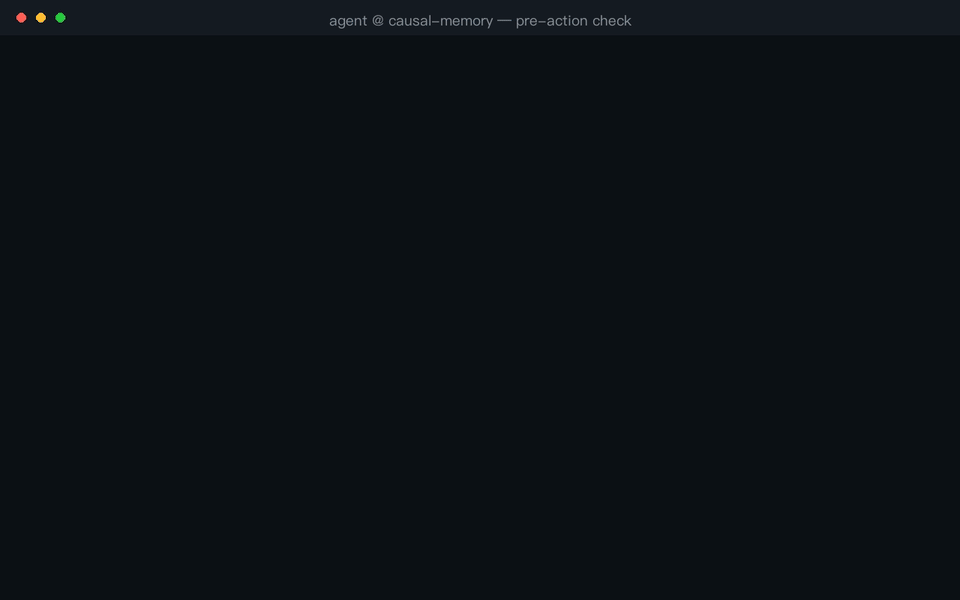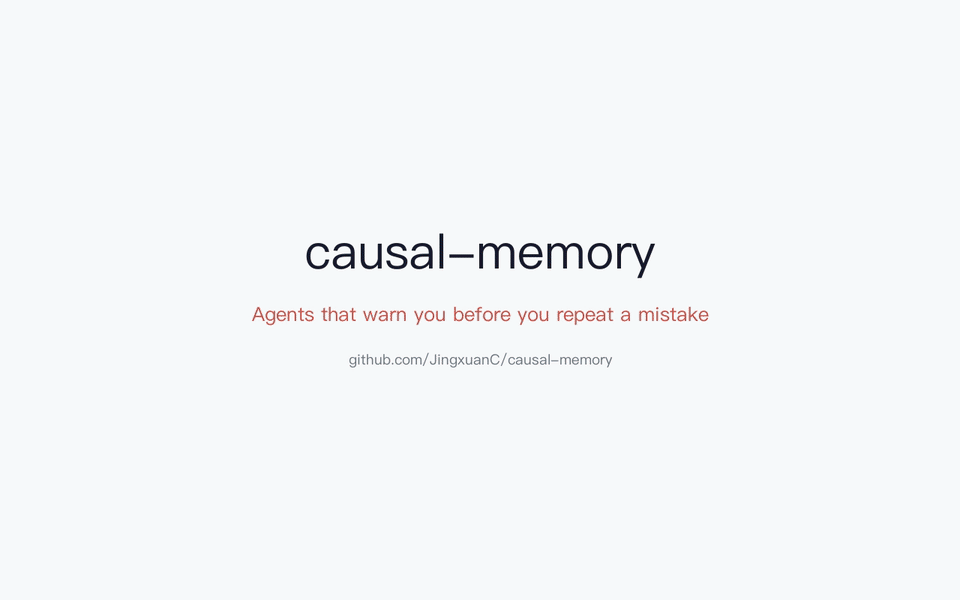
30-second single scene — the agent is about to git push --no-verify;
intervention_query fires a DANGER chain citing the lesson it recorded last
time ("production login failed for 40 minutes; emergency rollback"):
Download video ·
DANGER-scene screenshot ·
Regenerate: scripts/capture_demo30.py → scripts/render_demo30.py
A 21-second hands-on demo (real memory store, no mocks): pre-action warning
(intervention_query → DANGER chain) → experience recall (search_causal)
→ counterfactual comparison (counterfactual_query) → write loop
(record_decision → immediately searchable).
Download video ·
Warning-scene screenshot ·
Brand card ·
Regenerate: scripts/render_demo.py
Benchmarks
CausalEval — the causal memory benchmark (primary)
Most agent-memory benchmarks (LoCoMo, LongMemEval, Memora) test fact recall ("what is the user's preference"). causal-memory's differentiators — typed causal edges, inhibition, intervention prediction, cross-task transfer — are invisible on those suites. CausalEval measures them.
Design: the causal graph is the answer key. Typed DAGs are generated deterministically; conversations are narrated from the graph; gold answers are derived from graph structure — zero hand annotation, zero ambiguity.
CausalEval v13 (soft supersession) — 140 questions, 20 graphs (same LLM, same judge; v12 baseline was 70q/10 graphs; mem0 comparison ran on the 70q protocol):
…